Pocket AI Lab scans your device, tells you honestly which models will actually fit, downloads them straight from Hugging Face, and lets you chat with them fully offline.
Multi-backend inference — MLX, llama.cpp (GGUF), Core ML, and Apple Intelligence, switchable at runtime
Multimodal — text, images and video frames (vision models), speech-to-text (Whisper)
Import any model by link — paste a Hugging Face URL, pick a quantization, get a fit verdict before a single byte downloads
Honest memory budgets — recommendations are computed from the real per-process memory limits of your device, not marketing RAM numbers
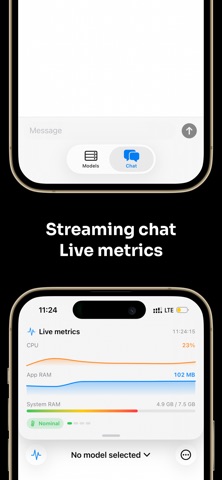
Live metrics — CPU, RAM and thermal pressure while the model is thinking
Streaming chat — token-by-token, with full conversation history on every backend